
Short answer, every rate read from the vendor’s own page on 4 September 2026: renting an RTX 4090 on Runpod Community Cloud costs $244.80 a month, and it only stops being the more expensive option above 1.75 billion tokens a month. That is 58.3 million a day, or 675 tokens a second sustained for 30 days, measured against Together AI’s Llama 3 8B Instruct Lite at $0.14 per million tokens in and $0.14 out. Against a frontier model the line moves by a factor of 37: an H100 PCIe at $1,432.80 a month passes gpt-6-astra at 48 million tokens, 18 tokens a second. Self-hosting beats an expensive model long before it beats a cheap one, which is the opposite of how the swap is usually sold.
| What you would rent | Per month | Instead of paying | Blended rate | Break-even |
|---|---|---|---|---|
| RTX 4090, 24GB | $244.80 | Together AI Llama 3 8B Instruct Lite | $0.14 per million | 1.75 billion tokens a month |
| RTX 4090, 24GB | $244.80 | OpenAI gpt-4o-mini | $0.375 per million | 653 million tokens a month |
| A100 PCIe, 80GB | $856.80 | OpenAI gpt-5.6-terra | $7.00 per million | 122 million tokens a month |
| H100 PCIe, 80GB | $1,432.80 | OpenAI gpt-6-astra | $30.00 per million | 48 million tokens a month |
This page is for a founder or an engineering lead holding an API invoice and wondering whether a GPU would be cheaper. It gives you the arithmetic to answer that for your own volume, on rates you can go and check, and it names the costs it leaves out rather than burying them. For the wider set of tools you can run on your own hardware, read our guide to open source AI tools you can self-host.
The whole calculation, in one line
Monthly GPU rent divided by the price of a million tokens gives you the volume at which the two options cost the same. That is the entire model. Everything else on this page is either a rate that goes into it or a cost it does not capture.
The one judgement call inside it is the blended rate. APIs price input and output separately, and output costs more, so a break-even depends on the shape of your traffic. This article assumes an even split, which is why gpt-4o-mini at $0.15 in and $0.60 out is treated as $0.375 a million. If your workload is summarisation, where input dwarfs output, your real blended rate is lower and your break-even is further away than the row below says. If it is generation, it is closer. Redo the division with your own ratio; that is the point of showing it.
Why the denominator is 720 hours, and why that is the honest one
A rented GPU bills for the hours it exists, not the hours it works. Leave an RTX 4090 running for a 30 day month and you are charged for 720 hours whether it served one request or ten million. An API bills for tokens and charges $0 for an idle hour.
That asymmetry is the reason the break-even sits so far out, and it is the part most comparisons quietly drop. A calculator that assumes your GPU is busy whenever you have work for it is pricing a machine nobody rents. The 720 hour month is what the invoice says.
Eight pairings, and the sustained rate each one demands
The last column is the one worth sitting with. A monthly token count is hard to feel. The same figure divided by 86,400 seconds in a day is a rate you can hold against any benchmark you trust, and it is arithmetic on the two columns to its left rather than a throughput claim from us.
| Rent this | Per month | Instead of | Blended rate | Tokens a month | Sustained, every second |
|---|---|---|---|---|---|
| RTX 4090 | $244.80 | Llama 3 8B Instruct Lite | $0.14 | 1.75 billion | 675 a second |
| RTX 4090 | $244.80 | gpt-4o-mini, Batch API | $0.1875 | 1.31 billion | 504 a second |
| RTX 4090 | $244.80 | gpt-4o-mini | $0.375 | 653 million | 252 a second |
| RTX 4090 | $244.80 | gpt-5.6-luna | $0.70 | 350 million | 135 a second |
| A100 PCIe | $856.80 | Llama 3.3 70B | $1.04 | 824 million | 318 a second |
| A100 PCIe | $856.80 | gpt-5.6-terra | $7.00 | 122 million | 47 a second |
| H100 PCIe | $1,432.80 | gpt-5.6-sol | $12.00 | 119 million | 46 a second |
| H100 PCIe | $1,432.80 | gpt-6-astra | $30.00 | 48 million | 18 a second |
Read the top and the bottom of that table together. To beat Llama 3 8B Instruct Lite you need 675 tokens a second out of a $0.34 an hour card, without a pause, for a month. To beat gpt-6-astra you need 18 a second out of an H100 PCIe. Those are different businesses. The first is a serious infrastructure commitment. The second is a background job.
Google’s own answer for this query, captured 31 August 2026, put the crossover at “tens of millions of tokens per day”. Against the open-weight APIs that is right: 58.3 million a day. Against gpt-6-astra it is 37 times too high, because the answer treats a single number as though both sides of the comparison were fixed. Neither is.
What the saving is, once you are past the line
Break-even is the point where the two invoices match. What matters after that is the gap, and it widens fast, because one side of it is a fixed $244.80 and the other is a multiplication.
| Tokens a month | Llama 3 8B Instruct Lite | gpt-4o-mini | gpt-5.6-luna | RTX 4090 rent | Against gpt-4o-mini |
|---|---|---|---|---|---|
| 250 million | $35 | $93.75 | $175 | $244.80 | $151.05 more |
| 500 million | $70 | $187.50 | $350 | $244.80 | $57.30 more |
| 1 billion | $140 | $375 | $700 | $244.80 | $130.20 saved |
| 2 billion | $280 | $750 | $1,400 | $244.80 | $505.20 saved |
| 5 billion | $700 | $1,875 | $3,500 | $244.80 | $1,630.20 saved |
Against gpt-4o-mini, the RTX 4090 stops costing more somewhere between 500 million and 1 billion tokens a month, and at 5 billion it is $1,630.20 a month better, $19,562.40 a year. Every additional billion tokens costs $375 on that API and nothing at all in rent, right up to the moment one card stops keeping up and the rent steps by another $244.80.
That step is the part the arithmetic cannot give you, and it is why the right-hand column of the table above is a ceiling rather than a forecast. Against Llama 3 8B Instruct Lite at $0.14 a million, the saving at 5 billion tokens is $455.20 a month, which is the same trade at 28 percent of the margin, and a great deal less room to absorb a second card.
What a million tokens costs, on the day this was written
| Vendor | Model | Input per million | Output per million | Blended |
|---|---|---|---|---|
| OpenAI | gpt-6-astra | $10.00 | $50.00 | $30.00 |
| OpenAI | gpt-5.6-sol | $4.00 | $20.00 | $12.00 |
| OpenAI | gpt-5.6-terra | $2.00 | $12.00 | $7.00 |
| OpenAI | gpt-5.6-luna | $0.20 | $1.20 | $0.70 |
| OpenAI | gpt-4o-mini | $0.15 | $0.60 | $0.375 |
| OpenAI | gpt-4o-mini, Batch API | $0.075 | $0.30 | $0.1875 |
| OpenAI | gpt-5-nano | $0.05 | $0.40 | $0.225 |
| Together AI | Llama 3.3 70B | $1.04 | $1.04 | $1.04 |
| Together AI | Llama 3 8B Instruct Lite | $0.14 | $0.14 | $0.14 |
| Together AI | DeepSeek V4 Flash 0731 | $0.14 | $0.28 | $0.21 |
| Together AI | Qwen3.5 9B | $0.17 | $0.25 | $0.21 |
The spread across that table is a factor of 214. That single fact does more work than any hardware decision. Moving from gpt-6-astra to Llama 3 8B Instruct Lite cuts a token bill by more than renting any card on this page, takes an afternoon rather than a quarter, and can be reversed by changing one string.
Two of these rates have a published end date on them
A break-even is a comparison between two prices, and a comparison is only as durable as the less durable price in it. GPU rent by the hour has no stated expiry. Two of the API-side rates in this article do, and both vendors print the date themselves.
- OpenAI gpt-5.6-sol: the page says “GPT-5.6 Sol’s promotional pricing is available at least through November 21, 2026”. Printed under the flagship pricing card. The $4.00 input and $20.00 output rate this article uses for gpt-5.6-sol is the promotional rate, and OpenAI names the date it is guaranteed to.
- Together AI dedicated NVIDIA HGX H100: the page says “PROMOTION VALID UNTIL 09/30/26”. On 31 August 2026 our capture of this row read $5.49 an hour. On 4 September 2026 the $5.49 is struck through and the live rate is $3.99, with an end date on the card.
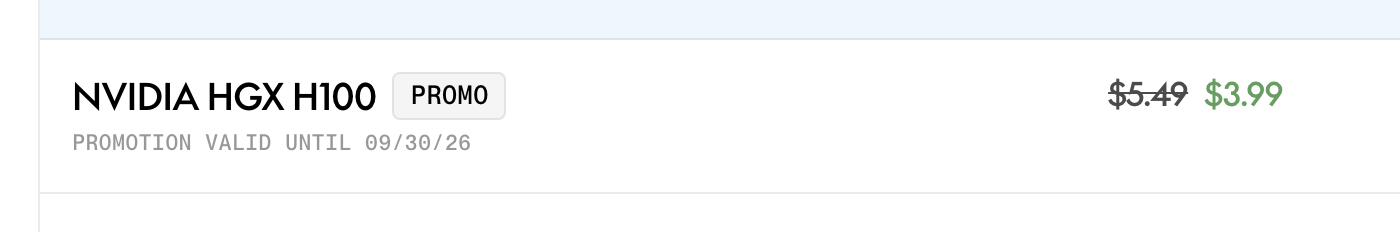
That is a 27 percent difference in the cost of the same hardware, landing between our two readings four days apart, on a page that tells you when it goes away. If you are building a business case on any rate in this article, note which side of it has a date attached. In this comparison it is the API side and the dedicated-capacity side, not the hourly GPU.
What a GPU hour costs, and the toggle that changes it
Runpod sells the same cards on two tiers. Community Cloud is capacity in other people’s data centres and is the cheaper of the two on every row below. Secure Cloud is Runpod’s own, and the pricing page opens on it. That default works in your favour rather than against it, which is unusual enough to say out loud: a screenshot of this page taken without touching anything understates the saving.
| GPU | VRAM | Community per hour | Secure per hour | Community per 720h month | Secure per 720h month |
|---|---|---|---|---|---|
| RTX A5000 | 24GB | $0.16 | $0.27 | $115.20 | $194.40 |
| RTX 3090 | 24GB | $0.22 | $0.50 | $158.40 | $360 |
| RTX A6000 | 48GB | $0.33 | $0.53 | $237.60 | $381.60 |
| RTX 4090 | 24GB | $0.34 | $0.74 | $244.80 | $532.80 |
| L40S | 48GB | $0.79 | $0.99 | $568.80 | $712.80 |
| A100 PCIe | 80GB | $1.19 | $1.39 | $856.80 | $1,000.80 |
| H100 PCIe | 80GB | $1.99 | $2.89 | $1,432.80 | $2,080.80 |
| H200 | 141GB | $3.59 | $4.59 | $2,584.80 | $3,304.80 |
Every one of those hourly rates matched what we recorded on 31 August 2026 exactly, on both tiers. Over the same four days the API side gained a model and a dedicated GPU row moved by 27 percent. Hourly GPU rent is the stable half of this comparison.
The third option, which the question usually leaves out
“Self-host or use an API” is a false pair. The same Runpod page prices a middle option: serverless GPUs, billed only while a request is running. The hourly rate is roughly three times the always-on rate, and the idle hours cost $0.
Which means there is a second break-even, and it is not about tokens at all. It is about how much of the month your GPU is actually busy. Divide the always-on monthly rent by the serverless hourly rate and you get the number of busy hours at which the two cost the same.
| GPU | Always-on, 720h month | Serverless tier | Serverless per hour | Busy hours that cost the same | Share of the month |
|---|---|---|---|---|---|
| RTX A6000 | $237.60 | A6000, A40 | $1.22 | 195 hours | 27% |
| RTX 4090 | $244.80 | 4090 | $1.10 | 223 hours | 31% |
| RTX 3090 | $158.40 | L4, A5000, 3090, MIG 24GB | $0.69 | 230 hours | 32% |
| H100 PCIe | $1,432.80 | H100 | $4.79 | 299 hours | 42% |
| A100 PCIe | $856.80 | A100 | $2.72 | 315 hours | 44% |
| L40S | $568.80 | L40, L40S, 6000 Ada, MIG 48GB | $1.75 | 325 hours | 45% |
| H200 | $2,584.80 | H200 | $5.93 | 436 hours | 61% |
The band runs from 27 percent to 61 percent. Below roughly a third utilisation, an always-on pod is the more expensive way to serve the same traffic on the same hardware from the same vendor. For an RTX 4090, the line is 223 busy hours out of 720.
This is the honest answer to most of the traffic that asks this question. A workload with real but bursty volume does not have to choose between a token bill and a machine that bills through the night. It is also the reason the 1.75 billion figure at the top of this page should be read as a ceiling on the always-on case rather than as the price of running your own model.
The checkbox on the API side that moves the line by 100 percent
Before renting anything, look at what your own side of the comparison can be made to cost. OpenAI prices a Batch tier at exactly half the standard rate for work that tolerates a queue: gpt-4o-mini drops from $0.15 and $0.60 to $0.075 and $0.30.
Halve the API rate and you double the volume needed to justify the GPU. The same $244.80 RTX 4090 that breaks even at 653 million tokens against the standard rate needs 1.31 billion against the Batch rate, which is 43.5 million a day and 504 tokens a second sustained. For any offline job, classification, enrichment, backfills, evaluation runs, that one setting is a larger saving than the hardware decision and it takes an afternoon.
What actually runs on the GPU, and what it costs to licence
The rent above buys hardware. The serving software is free, and 4 of the 5 projects below carry a licence with no conditions attached to commercial use. We checked each one against GitHub’s own API on 4 September 2026 rather than trusting the badge on the page.
| Tool | What GitHub reports | Role | Stars | AIRR score |
|---|---|---|---|---|
| LocalAI | MIT |
An OpenAI compatible endpoint, so existing code points at it without a rewrite. | 48,855 | 7.8 |
| vLLM | Apache-2.0 |
High throughput serving. The default choice when the box has to answer many requests at once. | 90,964 | 7.5 |
| Ollama | MIT |
Single box local serving, one command to pull and run a model. | 180,124 | 7.3 |
| Ray | Apache-2.0 |
Distributed execution for when one machine stops being enough. | 43,700 | 7.2 |
| Open WebUI | NOASSERTION |
The chat front end your staff actually see in front of the model. | 150,908 | 7.3 |
4 of those 5 return a real SPDX identifier. Open WebUI returns NOASSERTION, which GitHub’s web interface renders as the word “Other”, and it is the one on this list whose terms restrict what a company may do with it. That pattern holds across the wider catalogue and we set it out in our guide to open source AI tools you can self-host. It does not change the arithmetic on this page, because a licence condition is not a monthly cost, but it does change whether a plan survives contact with a lawyer.
Five costs this arithmetic does not contain
The table at the top is a comparison of two invoices. It is not a comparison of two situations. These are the gaps, named without invented numbers in them.
- Electricity. Rented hourly GPUs include power in the rate. An owned box does not, and we have no verifiable figure for a machine we do not run.
- The engineer. Somebody has to patch, restart and monitor the server. That cost is real, we will not invent an hourly rate for it, and it is the reason a saving on this page is not the same as a saving in practice.
- Throughput. How many tokens a second a given GPU serves depends on the model, the quantisation, the batch size and the server. We have not measured it, so the break-even is stated in tokens and you supply the rate.
- Storage and egress. Runpod prices persistent storage separately, from $0.05 per GB a month, and that is on top of every rent figure here.
- Quality. Nothing on this page says an open-weight model is as good as a closed one for your job. That needs a benchmark on your own data, and it is the first thing to test before any of this arithmetic matters.
The second one is the one that decides most real cases. A GPU you rent is a service you now operate. If the person who would operate it is also the person shipping your product, the $244.80 a month you saved has a price attached that does not appear on any invoice in this article.
When self-hosting wins without winning on cost
Every number above answers one question, and it is not always the question being asked. Three situations make self-hosting correct at volumes far below any line in this article.
Data that may not leave. If a contract, a regulator or a customer forbids sending the input to a third party, the break-even is irrelevant. The API option does not exist and the only figure that matters is the cheapest card that fits the model, which on the table above is RTX A5000 at $115.20 a month.
Weights you changed. A model fine-tuned on your own data is not available from anybody’s serverless endpoint at the open-weight rate. Once you are serving custom weights, the comparison is against a vendor’s dedicated capacity rather than its per-token rate, so it becomes hour against hour. Even then the managed option costs more: Together’s dedicated HGX H100 at $3.99 an hour is $2,872.80 a month against $1,432.80 for a Community H100 PCIe you run yourself, a factor of 2.0.
A price you can fix. Hourly GPU rent is the half of this comparison that did not move in four days. If your product’s margin depends on a unit cost you can promise a customer, that stability has a value the break-even table cannot show.
How we checked this
- We publish this break-even in tokens rather than in dollars per request because we have not benchmarked tokens per second for vLLM, Ollama or any other server on a rented GPU. Printing a throughput figure we did not measure would decide the whole answer for you on our guess.
- The one place AIRR runs open weights in production is speech. The site’s narration is generated locally on our own machine at no marginal cost per minute, which is the same trade this article describes, at a scale small enough that the hardware was already paid for.
- The Runpod page opens on Secure Cloud, the more expensive of its two tiers, so a screenshot of the default understates the saving rather than overstating it. Every Community figure here came from clicking that toggle.
Every rate was read in a rendered browser on 4 September 2026, with each toggle clicked rather than left at its default: both Runpod cloud tiers, the serverless tier, and OpenAI’s Standard and Batch tabs. The bundle behind this article was captured on 31 August 2026 and every row in it was read again on 4 September 2026 rather than carried forward, which is how the two expiry dates and the gpt-6-astra row were found.
Of the 10 pages Google’s own answer cited for this query on 31 August 2026, 0 were pricing pages belonging to a company that sells either side of this trade. No review site, no aggregator and no other article is a source for anything here. Where a figure could not be read from a primary it was cut, and the cuts are listed below rather than hidden.
What we could not verify, and therefore did not print
- Tokens per second, requests per second, or any throughput figure for vLLM, Ollama or Text Generation Inference on a named GPU. We have not benchmarked it on our own hardware and no vendor publishes a number we can cite.
- Electricity, bandwidth and engineer hours for an owned rather than rented box. Real costs, no verifiable figure, so they are named as factors without a number attached.
- Any claim that a specific open-weight model matches a specific closed model in quality. We hold no primary benchmark for that.
- The cost of buying a GPU outright. Street prices for the cards in this article vary by retailer and by week, and a purchase price we cannot read from one authoritative page is not a fact.
- Runpod’s Clusters and Provisioned Throughput tiers, and Together’s PTU calculator. All three price capacity rather than a single GPU, and the reservation terms that decide the real rate are behind a sales conversation.
Questions people ask about this
How much does it cost to host your own LLM?
On rented hardware, between $115.20 and $2,584.80 a month for a single GPU, read from Runpod Community Cloud on 4 September 2026: $0.16 an hour for a RTX A5000 up to $3.59 for an H200, times 720 hours. That is rent alone. It excludes storage, which Runpod prices separately from $0.05 per GB a month, and it excludes the person who keeps the server running.
How much does an LLM API cost?
Per million tokens, and the spread is a factor of 214 across the models we priced on 4 September 2026. The floor is Llama 3 8B Instruct Lite at $0.14 in and out. The ceiling is gpt-6-astra at $10.00 in and $50.00 out. Which one you are on decides the self-hosting question far more than which GPU you would rent.
Can I host my own LLM model?
Yes, and the software costs $0. 4 of the 5 serving projects we checked on 4 September 2026 carry a licence with no conditions on commercial use. The question is not whether you can, it is whether the volume justifies it: below roughly 58.3 million tokens a day against a cheap open-weight API, renting the GPU costs more than paying per token.
What is the difference between an LLM and an API?
The model is the thing that generates text. The API is one way to reach it, over the network, priced per token and billed at $0 when idle. Self-hosting is the other way: you rent or own the hardware, run a server such as vLLM or Ollama on it, and pay for time rather than for tokens. That difference in billing unit is the whole of this article: 720 hours a month are charged whether or not anything is asked of them.
At what volume does self-hosting an LLM become cheaper?
It depends entirely on what you are comparing against, which is why one number is always wrong. Against Llama 3 8B Instruct Lite at $0.14 a million, a $244.80 RTX 4090 needs 1.75 billion tokens a month, or 675 a second without stopping. Against gpt-6-astra at $30.00, an H100 PCIe needs 48 million, or 18 a second. Both verified 4 September 2026.
Is serverless GPU cheaper than renting a GPU by the month?
Below about 31 percent utilisation, yes, on Runpod’s own rates read 4 September 2026. An always-on RTX 4090 costs $244.80 a month; the serverless tier containing that card costs $1.10 an hour and charges nothing while idle, so the two meet at 223 busy hours out of 720. Across the 7 tiers we compared, the crossover sits between 27 and 61 percent.
Does the OpenAI Batch API change the break-even?
It doubles it. Batch is half the standard rate, so gpt-4o-mini at $0.375 blended becomes $0.1875, and the volume needed to justify a $244.80 RTX 4090 rises from 653 million tokens a month to 1.31 billion. For work that tolerates a queue, that setting is worth more than the hardware decision and it takes an afternoon rather than a quarter.
Do these prices stay the same?
Two of them have published end dates. OpenAI states that the gpt-5.6-sol rate used here is promotional and names 21 November 2026. Together AI’s dedicated HGX H100 row moved from $5.49 an hour on 31 August 2026 to $3.99 on 4 September 2026, with 30 September 2026 printed on the card as the end date. Every Runpod hourly rate we recorded on 31 August 2026 was unchanged on 4 September 2026. Re-derive the break-even against the rate you are actually being charged.
Sources
- OpenAI API pricing: developers.openai.com/api/docs/pricing, read on 4 September 2026.
- Together AI pricing: together.ai/pricing, read on 4 September 2026.
- Runpod pricing: runpod.io/pricing, read on 4 September 2026.
- Licence identifiers for vLLM, Ollama, LocalAI, Ray and Open WebUI: GitHub repository API, queried on 4 September 2026.
- r/AI_Agents discussion, Self Host LLM vs Api LLM, position 1 in the organic results for this query. Cited, not quoted: reddit.com returns HTTP 403 to anonymous reads.
- Manifold AI Learning, API vs Self-Hosted LLMs - The Wrong Choice Can Cost You $$$, 19:57, published 30 March 2026. Position 1 in the video pack for this query.
Comments
Sign in to join the discussion.
Login to comment